
Quick Diagnosis
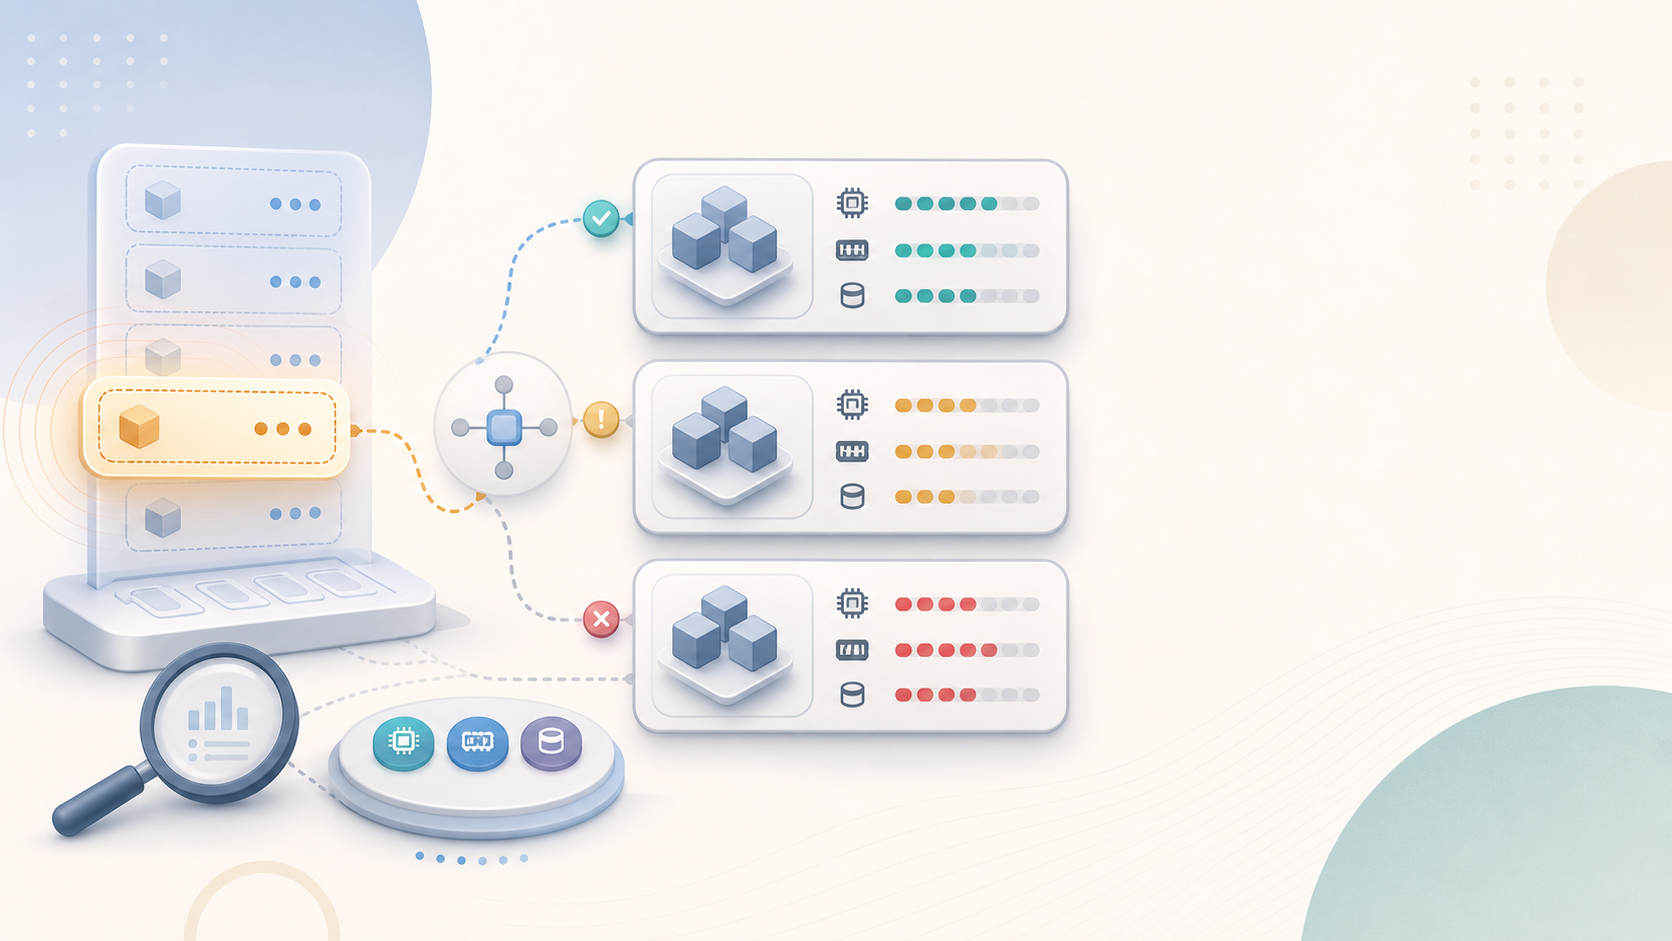
A Kubernetes Pod in Pending usually means the Pod has been accepted by the API server, but Kubernetes has not fully placed it on a node and prepared it to run. The most useful first move is not kubectl logs. It is kubectl describe pod, because the scheduler and storage events usually explain why placement is blocked.
Use this distinction before you start changing YAML:
| What you see | What it usually means | First place to look |
|---|---|---|
Pending with no node assigned | The scheduler cannot place the Pod | Events, resource requests, affinity, taints, node availability |
Pending with PVC messages | Storage binding or volume topology blocks scheduling | PVC, PV, StorageClass, volume node affinity |
ContainerCreating | The Pod was scheduled, but kubelet is still preparing it | Image pull, volumes, CNI, runtime setup |
ImagePullBackOff | The Pod was scheduled, but image pull failed | Registry, image name, secret, tag |
CrashLoopBackOff | The container starts and crashes repeatedly | Logs, app config, probes, memory |
Kubernetes documentation defines Pending as a phase where the Pod has been accepted by the cluster, but one or more containers have not been set up and made ready to run. That includes time spent waiting to be scheduled and time spent pulling images. In day-to-day troubleshooting, the key question is: did the scheduler choose a node yet?
If the Pod already has a node and is waiting on images, read the RepoNotes guide to Kubernetes ImagePullBackOff. If the Pod starts and then exits with memory pressure, use the Kubernetes OOMKilled guide. If the Pod is running but CPU behavior is strange, check Kubernetes CPU throttling.
First Commands to Run
Start by capturing the Pod status, node assignment, conditions, and recent events.
NS=default
POD=my-pending-pod

kubectl get pod "$POD" -n "$NS" -o wide
kubectl describe pod "$POD" -n "$NS"
kubectl get events -n "$NS" --sort-by=.lastTimestamp | tail -40Code language: Bash (bash)
If you do not know the namespace, list Pending Pods across all namespaces.
kubectl get pods -A --field-selector=status.phase=Pending -o wideCode language: Bash (bash)Then inspect the scheduler-facing details directly.
kubectl get pod "$POD" -n "$NS" -o jsonpath='{.spec.nodeName}{"\n"}'
kubectl get pod "$POD" -n "$NS" -o jsonpath='{range .status.conditions[*]}{.type}{"="}{.status}{" reason="}{.reason}{" message="}{.message}{"\n"}{end}'Code language: Bash (bash)
Interpret the output like this:
| Signal | Meaning |
|---|---|
.spec.nodeName is empty | The scheduler has not bound the Pod to a node yet. Focus on scheduling constraints. |
.spec.nodeName is set | The scheduler picked a node. Focus on kubelet setup, image pull, volumes, and CNI. |
PodScheduled=False | The scheduler rejected all available nodes. The message usually says why. |
Events mention FailedScheduling | Treat the event message as the primary clue. |
| Events mention PVC binding | Check the PVC/PV/StorageClass before changing CPU or memory. |
Read the Scheduler Message First
Most Pending investigations become easier when you treat the scheduler event as the source of truth. A message like this is not noise:
0/5 nodes are available: 3 Insufficient cpu, 2 node(s) had untolerated taint.
preemption: 0/5 nodes are available: 3 No preemption victims found for incoming pod.Code language: Bash (bash)
It says two things:
| Part of message | What it tells you |
|---|---|
0/5 nodes are available | The scheduler evaluated five nodes and rejected all of them. |
Insufficient cpu | At least some nodes do not have enough allocatable CPU for the Pod request. |
untolerated taint | Some nodes repel the Pod because the Pod lacks a matching toleration. |
No preemption victims | Kubernetes could not evict lower-priority Pods to make room. |
Do not jump straight to scaling the deployment. Fix the constraint the scheduler is naming.
Common Causes and Fixes
| Cause | Typical event text | What to check | Common fix |
|---|---|---|---|
| CPU or memory request too high | Insufficient cpu, Insufficient memory | Pod requests vs node allocatable | Lower requests, remove oversized replicas, add nodes, or enable capacity |
| PVC not bound | pod has unbound immediate PersistentVolumeClaims | PVC, PV, StorageClass | Fix StorageClass, provision PV, or wait for dynamic provisioning |
| Taint missing toleration | untolerated taint | kubectl describe node, Pod tolerations | Add a valid toleration or use a different node pool |
| Node selector mismatch | node(s) didn't match Pod's node affinity/selector | Labels, nodeSelector, affinity | Fix labels or relax hard affinity |
| Drained or unschedulable nodes | node(s) were unschedulable | kubectl get nodes | Uncordon nodes or add schedulable capacity |
| Host port conflict | didn't have free ports for the requested pod ports | hostPort, DaemonSets, node count | Remove hostPort, use a Service, or increase node count |
| Volume topology conflict | volume node affinity conflict | PV node affinity, zones | Match Pod placement to storage topology |
Cause 1: CPU or Memory Requests Are Too High
A Pod can stay Pending even when nodes look idle in a dashboard. The scheduler uses requested resources and allocatable capacity, not just current CPU usage. A node with low real-time CPU usage can still reject a Pod if its requested CPU is already reserved by other Pods.
Check the Pod requests.
kubectl get pod "$POD" -n "$NS" -o jsonpath='{range .spec.containers[*]}{.name}{" cpu="}{.resources.requests.cpu}{" memory="}{.resources.requests.memory}{"\n"}{end}'Code language: Bash (bash)Check node allocatable capacity.
kubectl describe nodes | grep -E 'Name:|Allocatable:|cpu:|memory:'Code language: Bash (bash)If metrics-server is installed, compare live usage too, but do not use it as the only scheduling signal.
kubectl top nodes
kubectl top pods -A --sort-by=cpuCode language: Bash (bash)
Fix options:
| Fix | Use when |
|---|---|
| Reduce resource requests | The request is accidentally oversized, such as 4 CPU for a small worker. |
| Add or scale nodes | The request is valid and the cluster lacks capacity. |
| Move workload to a larger node pool | The workload needs large contiguous CPU or memory. |
| Set realistic requests and limits | The manifest has missing or copy-pasted values. |
Be careful with the “just remove requests” shortcut. It may get the Pod scheduled, but it can make resource contention worse later. If the workload is already running but throttled, use the CPU throttling guide to diagnose runtime CPU behavior separately.
Cause 2: PVC Is Unbound
Storage is one of the easiest Pending causes to miss. The Pod can be valid, but if it references a PersistentVolumeClaim that is not bound, scheduling may stop with a message like:
pod has unbound immediate PersistentVolumeClaimsCode language: Bash (bash)Check the claims in the namespace.
kubectl get pvc -n "$NS"
kubectl describe pvc -n "$NS"Code language: Bash (bash)
Then check the StorageClass and available PVs.
kubectl get storageclass
kubectl get pv
kubectl describe pv PV_NAMECode language: Bash (bash)
Kubernetes PersistentVolumeClaims request storage and bind to PersistentVolumes. If no matching volume exists, or dynamic provisioning is not available for the requested StorageClass, the claim can remain unbound. The Kubernetes docs note that claims remain unbound indefinitely if a matching volume does not exist.
Fix options:
| Problem | Fix |
|---|---|
| Missing default StorageClass | Set storageClassName explicitly or configure a default StorageClass. |
| PVC requests too much storage | Lower the request or provision a larger PV. |
| Access mode mismatch | Use a PV/StorageClass that supports the requested access mode. |
| Static PV selector mismatch | Fix labels, selector, storageClassName, or claimRef. |
| Dynamic provisioner failure | Check CSI controller logs and StorageClass parameters. |
Cause 3: Taints and Tolerations Do Not Match
Taints let nodes repel Pods. Tolerations let Pods schedule onto nodes with matching taints, but they do not guarantee scheduling. If every suitable node has a NoSchedule taint that the Pod does not tolerate, the Pod stays Pending.
Check taints on nodes.
kubectl describe node NODE_NAME | grep -i taintsCode language: Bash (bash)Check tolerations on the Pod.
kubectl get pod "$POD" -n "$NS" -o yaml | sed -n '/tolerations:/,/containers:/p'Code language: Bash (bash)A typical toleration looks like this:
tolerations:
  - key: "dedicated"
    operator: "Equal"
    value: "batch"
    effect: "NoSchedule"Code language: YAML (yaml)
Fix options:
| If the taint is intentional | If the taint is accidental |
|---|---|
| Add a matching toleration to the workload. | Remove or correct the taint. |
| Also use node affinity if the workload must run only on that node pool. | Uncordon or repair the node pool. |
| Keep dedicated node pools explicit. | Avoid broad tolerations that let any Pod land on protected nodes. |
Do not add blanket tolerations just to make the event disappear. A toleration that matches too much can move the workload onto GPU, infra, or dedicated nodes where it does not belong.
Cause 4: Node Selector or Affinity Is Too Strict
A hard nodeSelector or required node affinity can exclude every node. This is common after node pool migrations, label renames, or copy-pasted manifests.
Inspect the Pod constraints.
kubectl get pod "$POD" -n "$NS" -o yaml | sed -n '/nodeSelector:/,/tolerations:/p'
kubectl get pod "$POD" -n "$NS" -o yaml | sed -n '/affinity:/,/containers:/p'Code language: Bash (bash)
List node labels.
kubectl get nodes --show-labelsCode language: Bash (bash)If the event says nodes did not match node affinity or selector, compare exact label keys and values. Kubernetes labels are case-sensitive and key-sensitive. nodepool=apps is not the same as node-pool=apps.
Fix options:
| Problem | Fix |
|---|---|
| Label changed during node pool migration | Update the manifest or restore the label. |
| Required affinity is too narrow | Convert part of it to preferred affinity. |
| Pod targets a retired node pool | Update the selector to the active node pool. |
| You need a specific topology | Make the topology rule explicit and document it. |
If this is your main issue, the RepoNotes guide to Kubernetes Node Selectors is the adjacent deep dive.
Cause 5: Nodes Are Unschedulable, NotReady, or Under Pressure
A cluster can have nodes and still have no usable scheduling target. Nodes may be cordoned, drained, NotReady, or tainted because of pressure conditions.
Check node status.
kubectl get nodes
kubectl describe node NODE_NAMECode language: Bash (bash)
Look for these signals:
| Signal | Why it matters |
|---|---|
SchedulingDisabled | The node is cordoned and will not accept new Pods. |
NotReady | The scheduler may avoid the node or the node may have taints. |
DiskPressure | Kubernetes can block new Pods and evict existing ones. |
MemoryPressure | BestEffort Pods may be blocked from scheduling. |
node.kubernetes.io/unschedulable | A built-in taint can stop scheduling. |
Fix options:
kubectl uncordon NODE_NAME
kubectl describe node NODE_NAMECode language: Bash (bash)
Use uncordon only when the node is actually ready to take traffic. If the node is under disk, memory, or PID pressure, fix the node condition first. For managed clusters, this may mean replacing the node, scaling the node group, or repairing the underlying disk/runtime issue.
Cause 6: HostPort or Topology Constraints Block Placement
hostPort binds a Pod port to a port on the node. That can make scheduling much harder because only one Pod per node can use the same host port. The Kubernetes debug docs call out hostPort as a common Pending cause.
Check whether the Pod uses hostPort.
kubectl get pod "$POD" -n "$NS" -o yaml | grep -n "hostPort"Code language: Bash (bash)Prefer a Service when you only need stable access to Pods.
apiVersion: v1
kind: Service
metadata:
  name: web
spec:
  selector:
    app: web
  ports:
    - port: 80
      targetPort: 8080Code language: YAML (yaml)
Use hostPort only when the workload truly needs the node network port. For most web services, the better fix is a Service, Ingress, Gateway API route, or cloud load balancer.
Topology spread constraints can also make a Pod Pending if the cluster cannot satisfy the placement rule. Inspect them if the scheduler event mentions topology, zones, or skew.
kubectl get pod "$POD" -n "$NS" -o yaml | sed -n '/topologySpreadConstraints:/,/containers:/p'Code language: Bash (bash)When Pending Is Not the Real Problem
Not every “stuck” Pod needs the same runbook. Use the status transition to avoid fixing the wrong layer.
| If the status is | Use this direction |
|---|---|
Pending and PodScheduled=False | Scheduler, resources, affinity, taints, PVCs |
ContainerCreating | Kubelet setup, CNI, volume mount, image pull |
ErrImagePull or ImagePullBackOff | Image name, registry auth, pull secret, tag |
CrashLoopBackOff | Application startup, command, config, probes, memory |
Running but slow | Requests, limits, CPU throttling, application behavior |
This matters because a “Pending Pod logs” search often leads people to the wrong command. If the container has not started, there may be no logs yet. The useful evidence is in events and Pod conditions.
Prevention Checklist
Use this checklist before a deployment hits production:
| Check | Why it helps |
|---|---|
| Set realistic CPU and memory requests | Prevents impossible scheduling and noisy overcommit. |
| Validate PVCs and StorageClasses in the target cluster | Catches storage gaps before rollout. |
| Keep node labels stable and documented | Reduces nodeSelector and affinity drift. |
| Avoid broad hard affinity | Leaves the scheduler enough room to place Pods. |
| Use taints and tolerations intentionally | Protects dedicated nodes without surprise Pending Pods. |
Avoid hostPort unless required | Prevents one-per-node placement bottlenecks. |
Watch FailedScheduling events in alerts | Detects capacity and policy issues early. |
A practical pre-deploy check can be as simple as server-side dry-run plus a namespace event watch during rollout.
kubectl apply --server-side --dry-run=server -f deployment.yaml
kubectl rollout status deployment/my-app -n production
kubectl get events -n production --sort-by=.lastTimestamp | tail -40Code language: Bash (bash)
FAQ
Why is my Kubernetes Pod stuck in Pending?
A Pod usually stays Pending because the scheduler cannot place it on a node or because a required setup step, often storage binding, has not completed. Run kubectl describe pod POD_NAME -n NAMESPACE and read the FailedScheduling or PVC-related events first.
Can I use kubectl logs on a Pending Pod?
Usually no. If no container has started, there are no container logs to read. Use kubectl describe pod, Pod conditions, and namespace events. If the Pod has moved to ContainerCreating, ImagePullBackOff, or CrashLoopBackOff, logs or container-specific events may become useful.
What does pod has unbound immediate PersistentVolumeClaims mean?
It means the Pod references a PVC that has not bound to a matching PersistentVolume. Check the PVC, StorageClass, dynamic provisioner, access mode, requested size, and available PVs. The Pod may not schedule until the storage claim can be satisfied.
How do I fix 0 nodes are available insufficient cpu?
Compare the Pod CPU request with node allocatable capacity and existing requested resources. Fix it by reducing an oversized request, moving the workload to a larger node pool, deleting unnecessary Pods, enabling autoscaling, or adding nodes. Do not rely only on current CPU usage graphs.
Are taints the same as node selectors?
No. A node selector or node affinity attracts a Pod to a set of nodes. A taint repels Pods unless they have a matching toleration. A Pod may need both: a toleration to be allowed onto a dedicated node pool and affinity to make sure it only lands there.

Leave a Reply